Drug discovery has traditionally progressed through lengthy and often fragmented cycles of hypothesis generation, experimentation, and refinement. AI can accelerate these cycles by identifying potential targets, designing molecules, generating predictions, prioritizing hypotheses, and uncovering relationships within complex biological data. But computational insights alone do not create medicines. They must be tested experimentally and interpreted by scientists within the appropriate biological context.
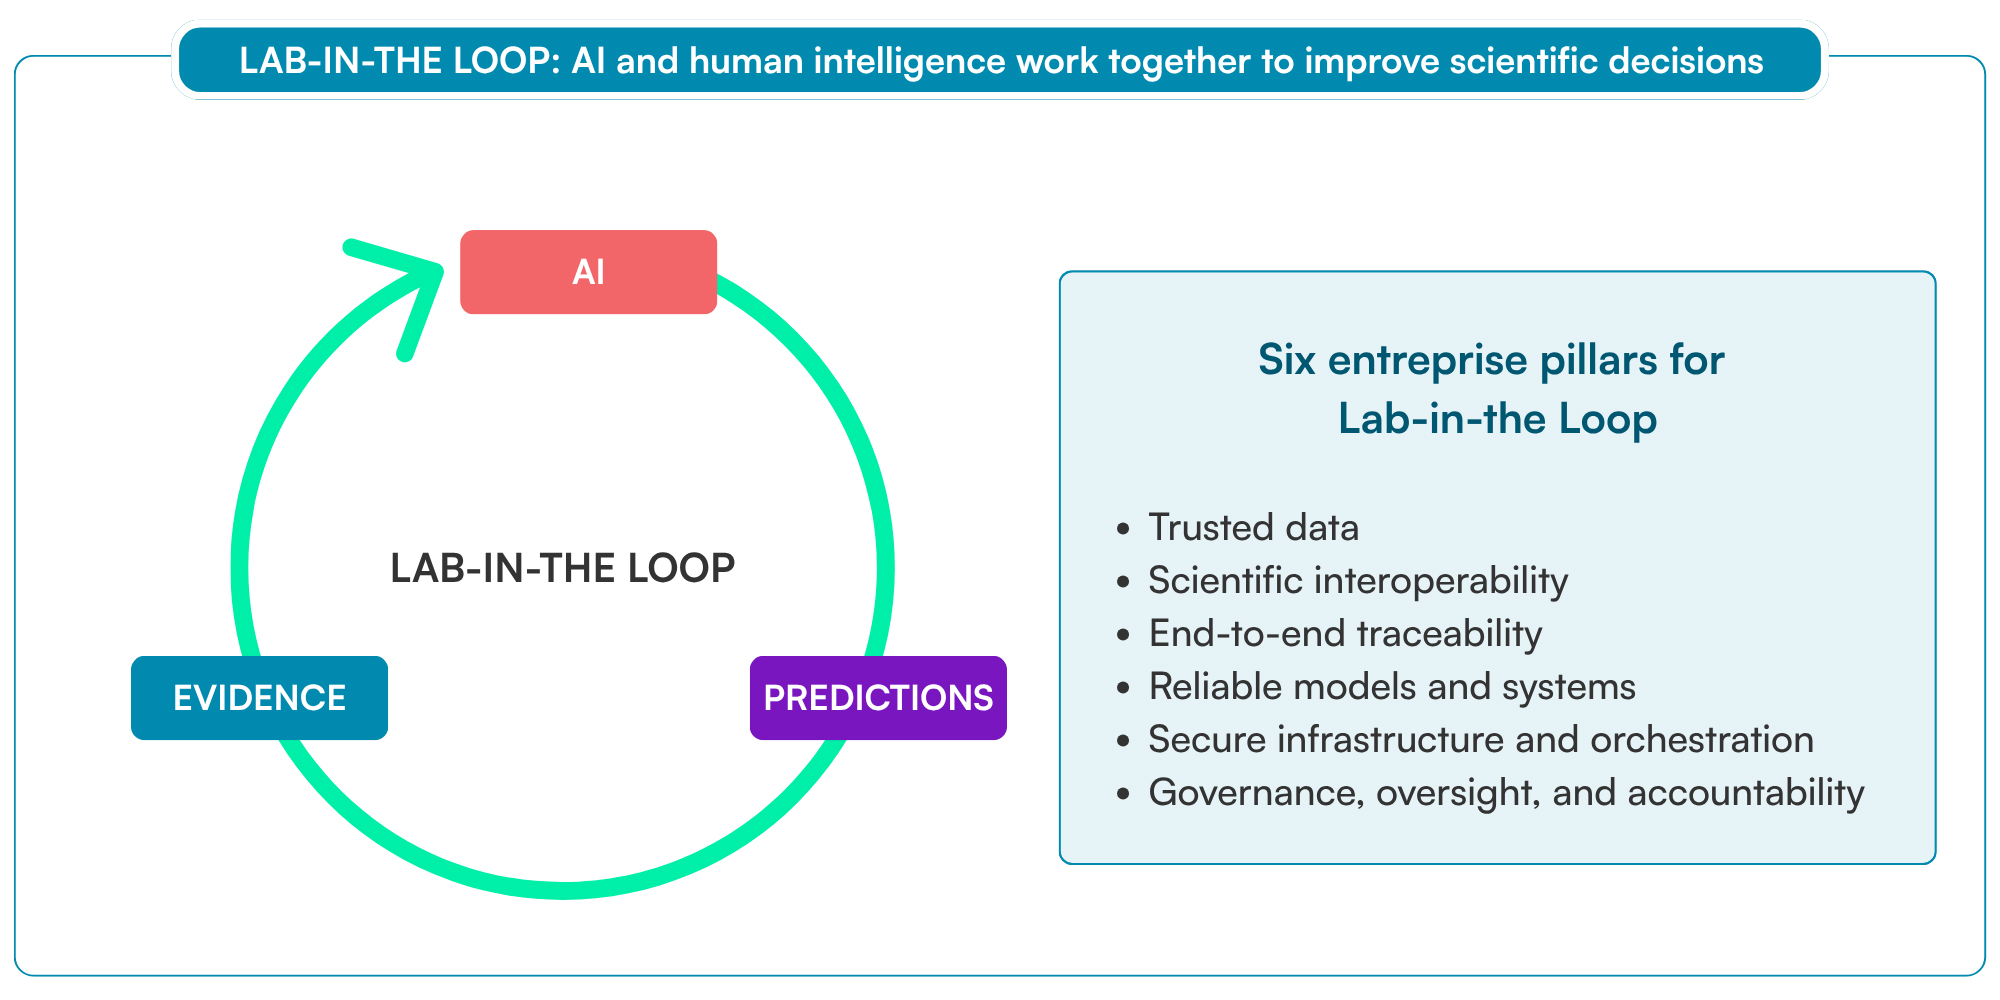
Lab-in-the-Loop closes this gap by integrating AI into a continuous cycle of experimentation, evidence generation, and learning. AI systems generate hypotheses or candidates, scientists select the experiments most likely to produce meaningful evidence, and laboratory teams and automated systems execute them. The resulting data informs the next experiment, scientific decision, or model refinement. The objective is not simply to run more experiments, but to learn more from each one. Negative and inconclusive results are therefore as important to the learning process as positive findings. When captured with the same rigor, provenance, and scientific context, they can reveal flawed assumptions, prevent repeated failures, and improve subsequent hypotheses and models.
Organizations are integrating both general-purpose frontier models and specialized biological foundation models into their Lab-in-the-Loop environments. Before applying these models across scientific workflows, life sciences companies must first ground them in, or adapt them using, their proprietary data, experimental evidence, and institutional knowledge. This helps ensure that model outputs reflect the company’s specific biological context, scientific priorities, and accumulated learning. Appropriately grounded or adapted models can then contribute across a growing range of scientific tasks, including knowledge synthesis, biological data analysis, hypothesis generation, protein analysis, molecular design, and property or activity prediction.
Beyond grounding models in their own proprietary data, pharmaceutical companies are also collaborating through federated learning and privacy-preserving platforms to train stronger models without exposing raw internal datasets. In one recent collaboration, AbbVie, Astex Pharmaceuticals, Bristol Myers Squibb, Johnson & Johnson, and Takeda used more than 20,000 proprietary protein–ligand structures to federatively fine-tune the open-source OpenFold3 Preview 2 model, without the underlying structures ever leaving their respective environments.1
Access to broader distributed datasets can strengthen individual models, but no single model—however capable—can address every task across the drug-discovery process. Lab-in-the-Loop environments should therefore incorporate agentic systems that dynamically direct each task to the most appropriate model, tool, dataset, or workflow.
Pharma’s Adoption of Closed-Loop Systems
Pharmaceutical companies are increasingly integrating AI with physical experimentation. Eli Lilly and NVIDIA have launched a co-innovation AI lab to create a continuous learning system that tightly connects Lilly’s agentic wet labs with computational dry labs.2 Roche is also using a lab-in-a-loop approach to retrain models with experimental results3.
“While AI can generate thousands of potential drug candidates, generation alone doesn’t guarantee a competitive advantage. The true bottleneck lies in building a robust therapeutic hypothesis rooted in causal biology—accurately identifying the right disease mechanism, target, biomarker, and patient profile.”
Recursion Pharmaceuticals, a leading TechBio, has built Recursion OS4, its integrated drug discovery and development platform that combines laboratory automation, large-scale biological experimentation, and machine learning within a continuous learning cycle. Recursion Pharmaceuticals reports running up to two million experiments each week and generating a proprietary dataset exceeding 50 petabytes.
Building a Trusted Enterprise Lab-in-the-Loop
The defining characteristic of an enterprise Lab-in-the-Loop is end-to-end traceability across the scientific lifecycle, connecting data, models, experiments, evidence, decisions, and outcomes. It should operate not as a collection of disconnected AI tools and data platforms, but as an enterprise continuous learning system that turns scientific questions, computational insights, and experimental evidence into better-informed decisions.
This capability requires a common enterprise framework for connecting and governing scientific data, models, instruments, laboratory systems, and workflows across teams and locations, supported by robust governance and a modern operating model. Governed catalogs should manage data, models, protocols, instruments, samples, and workflows as enterprise assets, with clear ownership, versioning, validation status, dependencies, and permitted uses. This enables scientists and AI systems to identify assets that are approved, compatible, and fit for purpose.